Two Ways to Measure a Hospital Chatbot
Why Message Counts Alone Do Not Show Performance
The number of chatbot messages usually rises after launch, whatever the chatbot achieves. More patients discover the channel, and some send several messages to get one answer. A busy chatbot may be helping patients, or it may be confusing them.
Performance means outcomes. Did patients get what they came for? Did enquiries become appointments and treatments? Did routine requests stop reaching the call centre? Did the chatbot answer correctly, or pass too many questions to staff? Message counts cannot answer these questions. Hospitals need measures that connect conversations to results, and measures that show how well the chatbot answers along the way.
The Outcome Dimension and the Accuracy Dimension
The first dimension looks at operations and business outcomes. It follows patients from using the chatbot, to becoming leads, to converting into appointments or treatments. It also counts the self-service transactions patients complete and compares performance across channels.
The second dimension looks at accuracy. It counts the questions patients ask, groups them by type and shows how many the chatbot answers and how many go to live agents or the call centre team. Each dimension needs the other. A chatbot with high usage but poor answers frustrates patients, while one with excellent answers but few leads may not be reaching the right patients.
The Operations and Business Outcome Dimension
Patient Usage
Start with how many patients use the chatbot. Track the number of conversations and the number of individual patients each month, and watch the trend. Steady growth suggests patients find the chatbot useful and return to it.
Look at when patients use it as well. The share of conversations outside working hours shows how much the chatbot extends the hospital’s availability. Usage on its own does not prove value, but it is the base for every other measure. Leads, conversions and self-service transactions are all read as a share of usage, so a reliable usage figure comes first. Without it, later percentages can mislead.
Leads Generated and Leads Converted
Many chats contain a genuine enquiry, such as interest in a procedure, a package or a specialist. Count how many leads the chatbot generates each month, including enquiries from chats that patients leave midway. These are passed to the outbound team for follow-up.
Then measure how many of those leads convert into appointments, admissions or procedures. Conversion is usually tracked by following each lead into the hospital’s CRM or HIS, where the outcome is recorded. Together, usage, leads and conversions form a simple funnel. A drop at any stage shows where to act. The guide to patient intent recognition in a hospital chatbot explains how these leads are identified.
Self-Service Transactions and Call Centre Load
Self-service transactions are tasks patients complete themselves in the chat, such as booking, rescheduling or cancelling appointments, requesting lab reports or past bills and booking home sample pickups. Count them by type each month.
Each completed transaction is a request the call centre team did not need to handle. Comparing these counts with call centre volumes for the same request types shows how much routine load the chatbot is taking away. This is an indicator rather than an exact saving, since patients may still call for other reasons. The guide to what patients can do on a hospital chatbot describes these self-service tasks.
Channel Performance
Patients reach the chatbot through WhatsApp, the website, Facebook and Instagram. Measuring usage, leads and conversions by channel shows which channel performs best for the hospital.
The results often differ. WhatsApp may bring the most conversations from existing patients, while website chat may bring new patients researching treatments. A channel with many conversations but few leads may need different options or content. A channel with fewer conversations but strong conversion may deserve more promotion. Channel data helps the hospital decide where to focus marketing effort and how to set up each channel. The guide to the one chat inbox for hospitals explains how conversations from every channel come together.
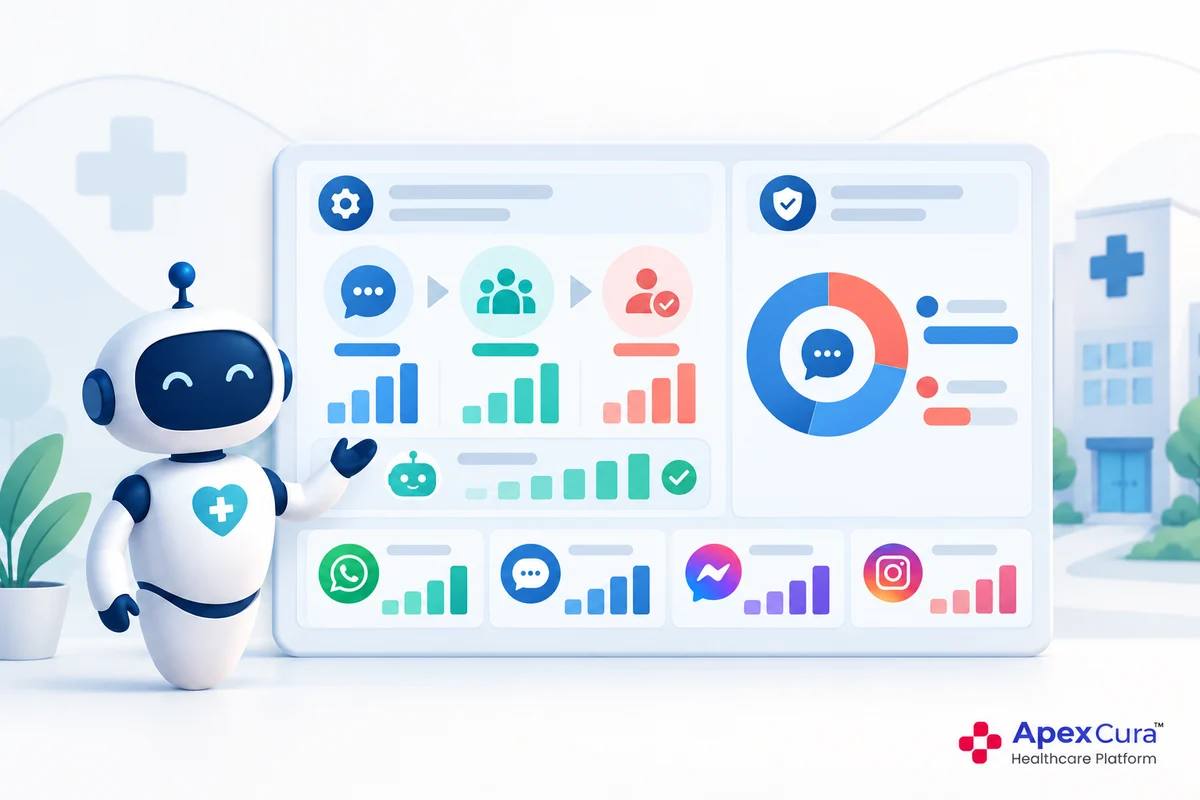
See how the GenAI Chatbot dashboards show conversations by channel, identified intents, questions answered and appointments booked in chat.
Explore Apex GenAI ChatbotThe Chatbot Accuracy Dimension
Questions Asked and Types of Questions
The accuracy dimension starts with what patients ask. Count the questions the chatbot receives and group them by type, such as doctor availability, appointments, packages, prices, reports, insurance and directions.
This shows what patients actually want from the hospital, which may differ from what the team expected. A rise in questions about one treatment may reflect a campaign or a new service. Frequent questions about directions may suggest the website could explain them better. Question types also guide which options the chatbot shows patients first, and which information deserves the most care in the knowledge base. Reviewing the mix each month keeps the hospital close to its patients’ real concerns.
Questions Answered by the Chatbot
Next, measure how many questions the chatbot answers from the hospital’s approved information, overall and by question type. This answer rate is a useful indicator of how complete and well organised the knowledge base is. Tracking it monthly shows whether improvements to the knowledge base are working.
A low answer rate for a particular type usually points to a gap: missing information, information worded differently from how patients ask or a live system that is not connected. Reviewing these by type shows exactly where to improve. The guide to the hospital chatbot knowledge base explains how to identify unanswered questions and improve the training on them.
Questions Diverted to Live Agents or the Call Centre
Finally, count the conversations diverted to live agents or the call centre team, and record why. Some diversions are planned. The hospital may route procedure costs or IVF enquiries to a counsellor by design, and some patients simply prefer a person.
Other diversions are unplanned. They happen when the chatbot cannot answer from approved information, or when a patient chooses “Chat with Live Agent” after an unhelpful answer. Separating planned from unplanned diversions matters. Planned diversions show the workflow working as intended. Unplanned ones show where the chatbot’s answers or knowledge base need attention. Tracking both over time shows whether the chatbot is handling more on its own.
Reviewing Both Dimensions Together
A Monthly Review That Leads to Action
Review both dimensions together every month, against a baseline from the first few months after launch. Reading them side by side often explains what one dimension alone cannot.
High usage with a low answer rate suggests gaps in the knowledge base. Good answers with low conversion may point to slow follow-up by the outbound team. A channel with many leads but few conversions may attract the wrong audience. Turn each finding into one specific change, such as adding information, adjusting chatbot options or speeding up call backs, and check its effect the following month. Treat all measures as indicators that guide decisions, not as exact figures.
Conclusion
Hospital chatbot performance is best measured in two dimensions. The operations and business outcome dimension tracks patient usage, leads generated, leads converted, self-service transactions that reduce call centre load and performance by channel. The accuracy dimension tracks the questions patients ask, how many the chatbot answers and how many go to live agents or the call centre. Reviewed together every month, they show where to improve. A hospital chatbot with performance measures built into its dashboards helps hospitals act on these insights.